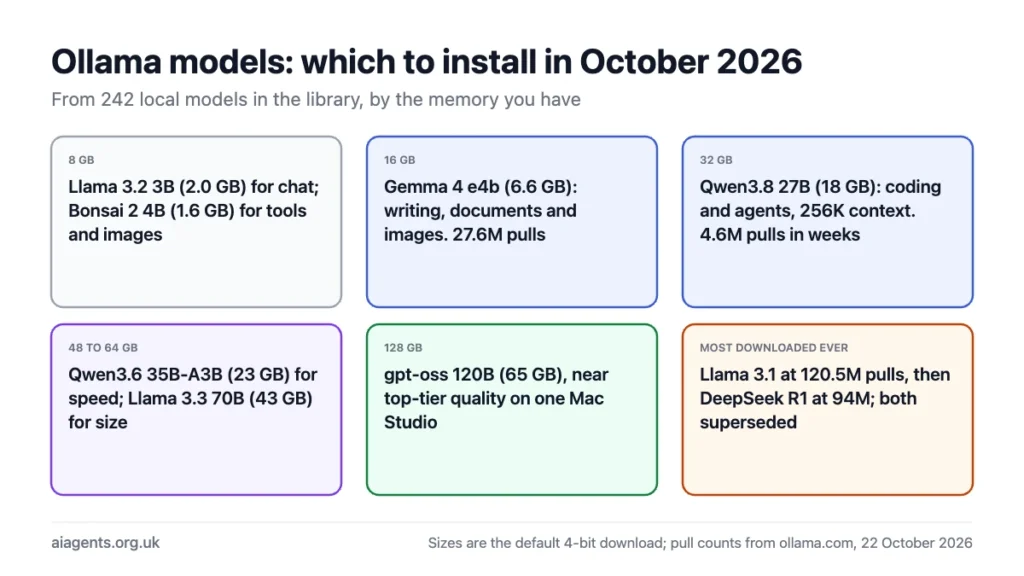
The Ollama library holds 258 models as of 22 October 2026, 242 of which run on your own machine, and the most downloaded is still Llama 3.1 with 120 million pulls. For a new Mac the four to know are Gemma 4 for everyday work and images, Qwen3.8 27B for coding and agents, gpt-oss 20B for reasoning and Bonsai 2 if you are short of memory. This page lists the 30 most pulled models with their download size, context window and job, then recommends one for each amount of memory. Pull counts and sizes come from the library itself and are refreshed monthly.
On this page
- How to read the library
- The 30 most downloaded Ollama models
- The best Ollama model for each amount of memory
- New this month
- Listing, pulling and removing models
- Frequently asked questions
How to read the library
Every entry on ollama.com/search has a name, a set of size tags such as 4b, 12b and 27b, and capability labels. Tools means it can call functions, which an agent such as OpenClaw needs. Vision means it reads images. Thinking means it reasons step by step before answering, which helps with maths and code and slows everything else. Embedding models turn text into numbers for search and are not chat models at all. Cloud means it runs on Ollama's servers, not yours, so your prompts leave the machine.
Pull counts are lifetime downloads, so old models such as Llama 3.1 and Gemma 2 sit high on the list long after better ones arrived. The table marks the ones I would still install today. The size column is the default download, which is the 4-bit file for nearly every model; the memory calculator turns a size into a yes or no for your Mac.
The 30 most downloaded Ollama models
| # | Model | Maker | Pulls | Sizes | Default download | Context | Can do | Install today? |
|---|---|---|---|---|---|---|---|---|
| 1 | llama3.1 | Meta | 120.5M | 8b, 70b, 405b | 4.9 GB (8b) | 128K | Tools | Only as a safe starter; Gemma 4 is better |
| 2 | deepseek-r1 | DeepSeek | 94M | 1.5b to 671b | 5.2 GB (8b) | 128K | Tools, thinking | Superseded by gpt-oss and Qwen3.8 |
| 3 | nomic-embed-text | Nomic | 92.3M | one size | 274 MB | 8K | Embedding | Yes, for document search |
| 4 | llama3.2 | Meta | 86M | 1b, 3b | 2.0 GB (3b) | 128K | Tools | Yes on 8 GB machines |
| 5 | qwen2.5 | Alibaba | 43.2M | 0.5b to 72b | 4.7 GB (7b) | 32K | Tools | No, use Qwen3.8 or Qwen3.6 |
| 6 | gemma3 | 41.3M | 270m to 27b | 3.3 GB (4b) | 128K | Vision | No, use Gemma 4 | |
| 7 | qwen3 | Alibaba | 41.1M | 0.6b to 235b | 5.2 GB (8b) | 40K | Tools, thinking | No, use Qwen3.8 |
| 8 | gemma2 | 35.4M | 2b, 9b, 27b | 5.4 GB (9b) | 8K | Chat only | No | |
| 9 | mistral | Mistral AI | 34M | 7b | 4.4 GB | 32K | Tools | No, use mistral-small |
| 10 | gemma4 | 27.6M | e2b, e4b, 12b, 26b, 31b | 6.6 GB (e4b) | 128K to 256K | Vision, tools, thinking, audio | Yes, the default for most Macs | |
| 11 | llama3 | Meta | 25.8M | 8b, 70b | 4.7 GB (8b) | 8K | Chat only | No |
| 12 | qwen3.5 | Alibaba | 23.1M | 0.8b to 122b | 6.6 GB (9b) | 256K | Vision, tools, thinking | Yes for 9b on 16 GB; otherwise Qwen3.8 |
| 13 | qwen2.5-coder | Alibaba | 22.7M | 0.5b to 32b | 4.7 GB (7b) | 32K | Tools | No, use qwen3-coder |
| 14 | phi4 | Microsoft | 7.8M | 14b | 9.1 GB | 16K | Chat only | No |
| 15 | mxbai-embed-large | Mixedbread | 16.1M | 335m | 670 MB | 512 | Embedding | Yes, alternative to nomic |
| 16 | llava | LLaVA team | 15.2M | 7b, 13b, 34b | 4.7 GB (7b) | 4K | Vision | No, Gemma 4 sees better |
| 17 | gpt-oss | OpenAI | 14.1M | 20b, 120b | 14 GB (20b) | 128K | Tools, thinking | Yes, 20b on 24 GB or more |
| 18 | qwen3-coder | Alibaba | 10.2M | 30b, 480b | 19 GB (30b) | 256K | Tools | Yes, for coding on 32 GB or more |
| 19 | glm-ocr | Z.ai | 8.5M | 0.9b | 2.7 GB | 128K | Vision, tools | Yes, for reading scans and PDFs |
| 20 | gemma | 8.4M | 2b, 7b | 5.0 GB (7b) | 8K | Chat only | No | |
| 21 | qwen | Alibaba | 8.1M | 0.5b to 110b | 4.5 GB (7b) | 32K | Chat only | No |
| 22 | bge-m3 | BAAI | 7.9M | 567m | 1.2 GB | 8K | Embedding | Yes, best for non-English search |
| 23 | llama2 | Meta | 7.6M | 7b, 13b, 70b | 3.8 GB (7b) | 4K | Chat only | No |
| 24 | qwen3.6 | Alibaba | 7.3M | 27b, 35b-a3b | 23 GB (35b-a3b) | 256K | Vision, tools, thinking | Yes, 35b-a3b is the fast pick on 48 GB |
| 25 | codellama | Meta | 7.3M | 7b to 70b | 3.8 GB (7b) | 16K | Chat only | No |
| 26 | qwen3-vl | Alibaba | 6.8M | 2b to 235b | 6.2 GB (8b) | 256K | Vision, tools, thinking | Yes, if images are the main job |
| 27 | qwen2 | Alibaba | 6.3M | 0.5b to 72b | 4.4 GB (7b) | 32K | Tools | No |
| 28 | tinyllama | TinyLlama | 6.3M | 1.1b | 638 MB | 2K | Chat only | No |
| 29 | mistral-nemo | Mistral AI and Nvidia | 5.7M | 12b | 7.1 GB | 128K | Tools | No, use mistral-small |
| 30 | minicpm-v | OpenBMB | 5.6M | 8b | 5.5 GB | 32K | Vision | No, Gemma 4 sees better |
Just outside the top 30 and worth knowing: qwen3.8 (4.6 million pulls in a few weeks, 27B, 18 GB, 256K context, vision, tools and thinking), llama3.3 70B (4.3 million, 43 GB, the standard 70B), mistral-small 24B (3.2 million, 14 GB, 32K context, tools) and qwen3-embedding (4.4 million, the newest embedding family). The Chinese models guide covers what running Qwen, DeepSeek and GLM locally does and does not send anywhere.
The best Ollama model for each amount of memory
A Mac gives a model about three quarters of its memory, so these picks leave room for a long conversation. The 4-bit default download is assumed throughout.
| Memory | Everyday chat and documents | Coding and agents | If you want the biggest that fits |
|---|---|---|---|
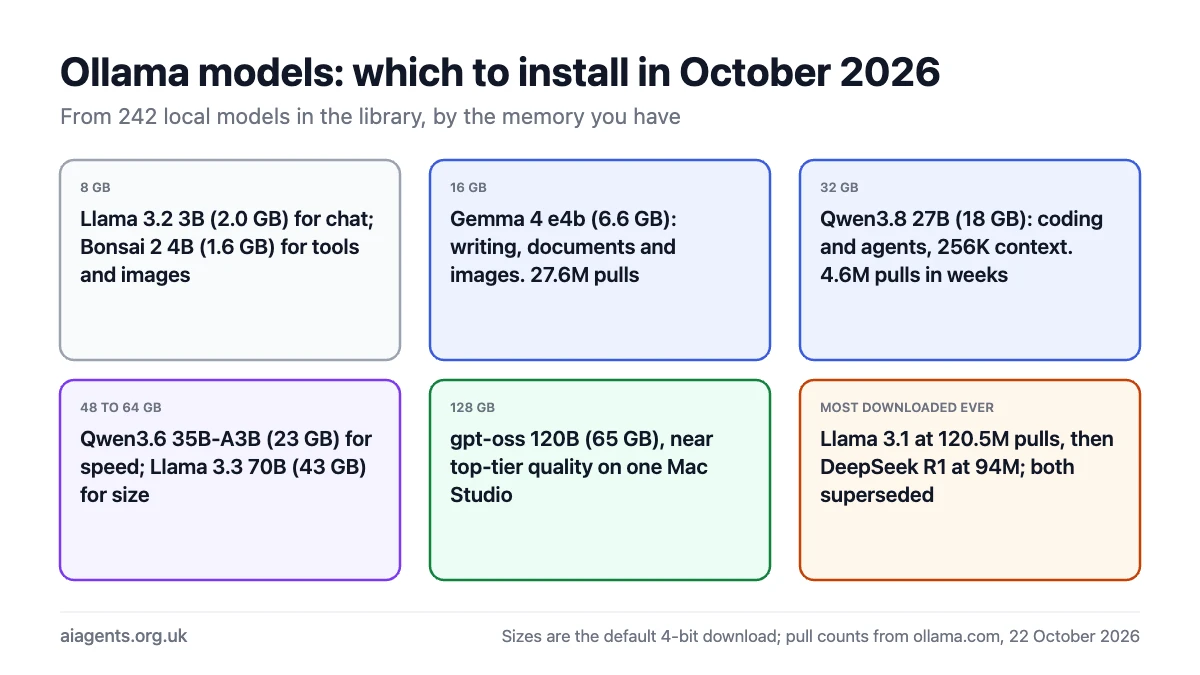
| 8 GB | llama3.2:3b (2.0 GB) | bonsai-2:4b (1.6 GB) | bonsai-2:9b (3.2 GB) |
| 16 GB | gemma4 (e4b, 6.6 GB) | qwen3.5:9b (6.6 GB) | bonsai-2:27b (8.3 GB) or gemma4:12b (8.0 GB) |
| 24 GB | gemma4:12b (8.0 GB) | gpt-oss:20b (14 GB) | mistral-small:24b (14 GB) |
| 32 GB | qwen3.8:27b (18 GB) | qwen3.8:27b (18 GB) | gemma4:31b (20 GB) or qwen3-coder:30b (19 GB) |
| 48 GB | qwen3.6:35b-a3b (23 GB), the fast one | qwen3.8:27b at 8-bit (30 GB) | nemotron-3.5-lightning (19 to 25 GB, 1M context) |
| 64 GB | llama3.3:70b (43 GB) | qwen3.8:27b at 8-bit (30 GB) | deepseek-r1:70b (43 GB) |
| 128 GB | gpt-oss:120b (65 GB) | gpt-oss:120b (65 GB) | qwen3.5:122b (81 GB) |
Add one embedding model whatever your memory: nomic-embed-text (274 MB) for English, bge-m3 (1.2 GB) for other languages. Apps such as Open WebUI and AnythingLLM use it to search your documents. Which machine to buy for each row is in which Mac or mini PC to buy for local AI.
New this month
Local models added or updated recently, from the library's "newest" view on 22 October 2026:
- bonsai-2 (Prism ML): a family of 2B to 27B models stored as ternary weights, so the 27B is only 8.3 GB and runs on a 16 GB Mac. Vision, tools and thinking. The most interesting arrival for small machines.
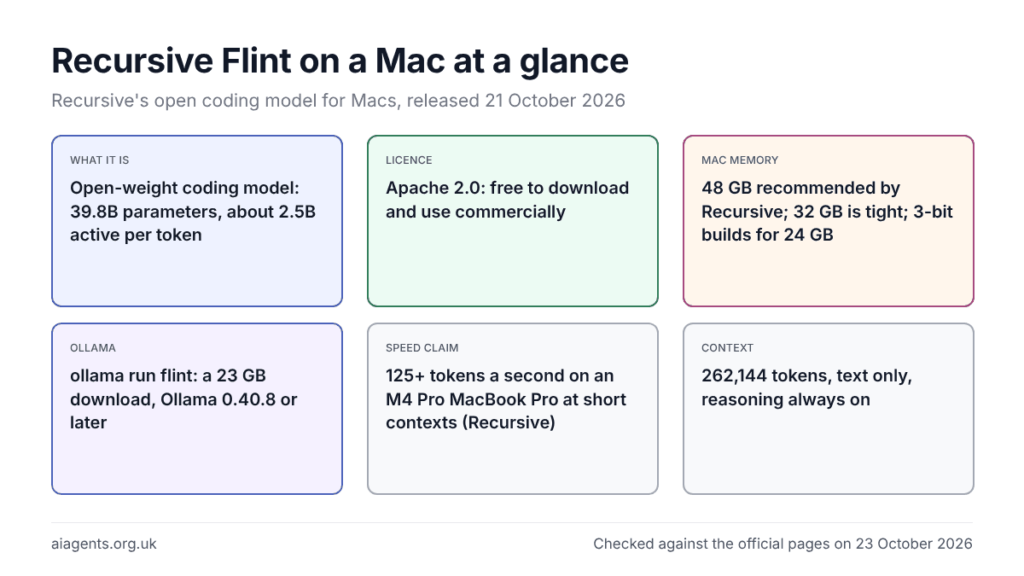
- flint (Recursive): a 40B coding model with only about 2.5B active per token, added on 21 October 2026. A 23 GB download that Recursive recommends running on 48 GB, with a claimed 125+ tokens a second on an M4 Pro MacBook Pro. See Recursive Flint on a Mac.
- nemotron-3.5-lightning, bolt and super (Nvidia): a 30B mixture-of-experts with a 1 million token context, a compact vision model and a 120B flagship.
- ornith (Deep Reinforce): 9B and 35B coding-agent models under an MIT licence, 658,000 pulls already.
- muse-glimmer (Meta): a 30B model distilled from Meta's Muse Spark for running agents on ordinary hardware; 18 GB, 128K context.
- embeddinggemma-2 (Google): embeddings for text, images and audio, from 270M parameters.
- A wave of "decision" models (tev1, nimble, clef, d1): small models that answer typed yes-or-no and classification questions in one pass, for routing and scoring rather than chat.
The cloud-only arrivals, DeepSeek V4.1 Flash, GLM 5.3, MiniMax M3.1 Flash and Mistral Large 4, run on Ollama's servers and are outside the scope of a local list. What those cost and where they run is in Ollama Cloud explained. For the Qwen 3.8 family on a Mac, see Qwen 3.8 on a Mac.
Listing, pulling and removing models
Four commands cover it. ollama list shows what is installed and how big each file is; ollama ps shows what is loaded in memory right now; ollama pull gemma4:12b downloads a specific size; ollama rm gemma3 deletes one. Models live in ~/.ollama/models on a Mac, and the troubleshooting page explains how to move them to an external drive. The rest of the commands are in the Ollama commands cheat sheet.
ollama list
ollama ps
ollama pull qwen3.8:27b
ollama rm llama3.1
Frequently asked questions
How do I see a list of Ollama models?
For every model you can download, browse ollama.com/search, which lists 258 models with size tags, capabilities and pull counts, and filter by Local to hide the cloud ones. For the models already on your computer, run ollama list in Terminal; it shows each model's name, size and when it was downloaded.
What is the best Ollama model?
For most people in October 2026, Gemma 4 on a 16 GB machine and Qwen3.8 27B on 32 GB or more. Gemma 4 handles writing, documents and images in a 6.6 GB download; Qwen3.8 is the strongest 27B model for coding and agent work. On 128 GB, gpt-oss 120B. The best model is always the biggest one that fits your memory with room to spare.
What is the most popular Ollama model?
Llama 3.1, with 120.5 million lifetime pulls, followed by DeepSeek R1 at 94 million and the nomic-embed-text embedding model at 92 million. Those counts reflect age as much as quality; among models released this year, Gemma 4 leads with 27.6 million and Qwen3.8 reached 4.6 million within weeks.
Which Ollama models support tools?
Models labelled "tools" in the library can call functions, which agents need. Current ones include Gemma 4, Qwen3.8, Qwen3.6, Qwen3.5, gpt-oss, qwen3-coder, mistral-small, Llama 3.3 and Llama 3.1. Older chat-only models such as Gemma 2, Llama 3 and Phi 4 cannot, so an agent built on them will fail at the first tool call.
Which Ollama models can see images?
Those labelled "vision": Gemma 4, Qwen3.8, Qwen3.6, Qwen3.5, qwen3-vl, Bonsai 2, glm-ocr and the older llava and minicpm-v. Gemma 4 is the best all-round choice; glm-ocr is a 2.7 GB specialist for scanned documents and PDFs.
What is the smallest useful Ollama model?
Bonsai 2 at 4B is 1.6 GB and still handles tools, images and reasoning, which makes it the best small model for an 8 GB machine. Llama 3.2 3B at 2.0 GB is the safe older choice. Anything under 1 GB, such as tinyllama, is for experiments rather than real work.
How often is this list updated?
Monthly, with the date at the top of the page. Pull counts change daily, so treat the ranking as a snapshot; the recommendations change only when a model is replaced by a better one at the same size.
Read next
- Ollama guide: install, run and manage local models
- Can my Mac run this model? Memory calculator
- Which Mac or mini PC to buy for local AI
- Ollama not working? Fixes for the common problems
- Is it safe to run Chinese AI models locally?
- Qwen 3.8 on a Mac: which build fits your memory
- Recursive Flint on a Mac: the fast 40B coding model
- Ollama commands cheat sheet
- Ollama Cloud explained: free tier, Pro prices and privacy
Sources
- Ollama library, local models: names, size tags, capabilities and pull counts for all 242 local models - read 22 October 2026
- Ollama library tag pages for gemma4, qwen3.8, qwen3.6, qwen3.5, gpt-oss, deepseek-r1, llama3.3, llama3.1, qwen3-coder, qwen3-vl, bonsai-2, mistral-small, nemotron-3.5-lightning, ornith, muse-glimmer and glm-ocr: download sizes and context lengths - read 22 October 2026