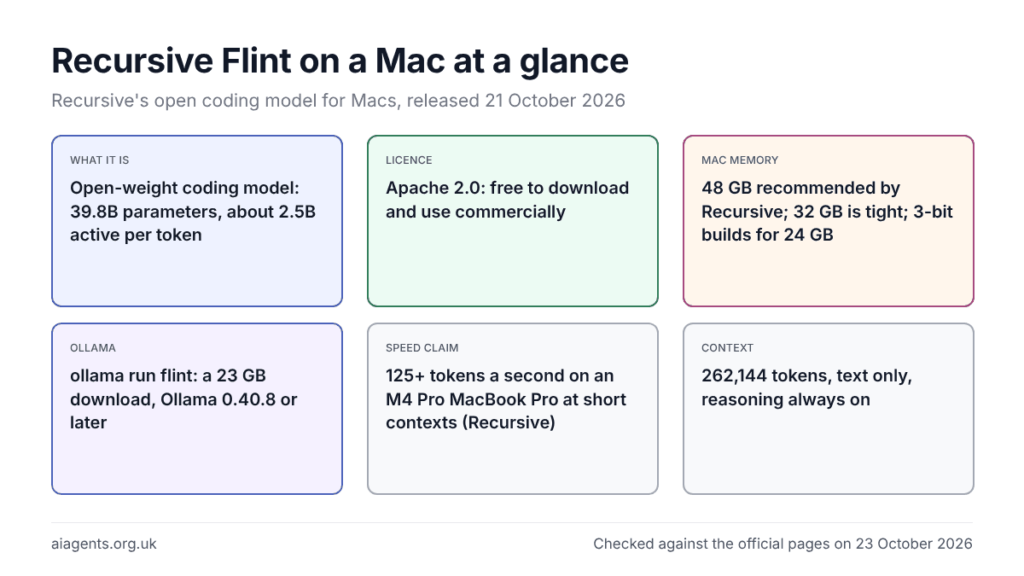
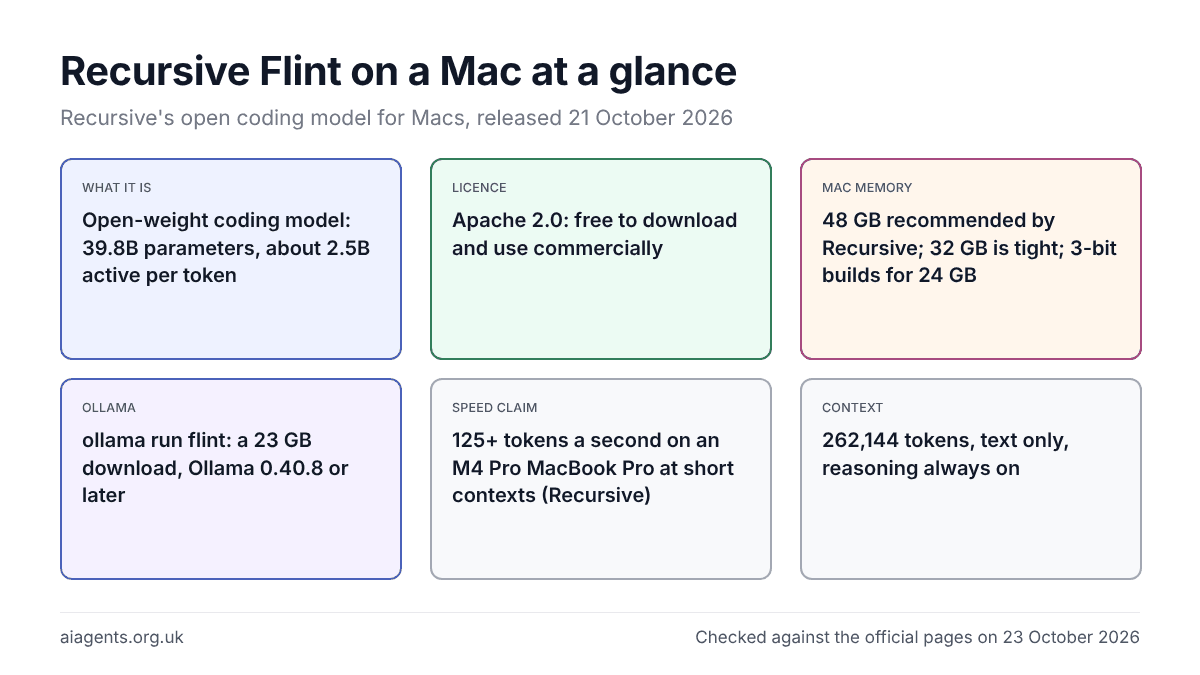
Recursive Flint is an open-weight coding model released on 21 October 2026 by Recursive, a San Francisco AI lab: 39.8 billion parameters, about 2.5 billion active per token, under Apache 2.0. On a Mac it is one command, ollama run flint, for a 23 GB download; Recursive recommends 48 GB of memory, 32 GB gets tight as the context grows, and 3-bit builds squeeze onto 24 GB. Recursive claims over 125 tokens a second on an M4 Pro MacBook Pro at short contexts, which an independent test matched, but long agent sessions run far slower. It is fast rather than the cleverest: Recursive's own chart puts the slower Qwen3.8-27B ahead on quality. Not sure how much memory your Mac has? Try the memory calculator.
On this page
- What is Recursive Flint?
- Which Mac runs Flint?
- How to run Flint with Ollama
- Run it in LM Studio or with MLX
- How fast is Flint on a Mac?
- Flint as a local coding agent
- How Flint compares
- How many people use Flint?
- What people say on Reddit and X
- Licence and safety: can you use Flint for work?
- Frequently asked questions
- Read next
- Sources
What is Recursive Flint?
Recursive Flint is a mixture-of-experts language model built for coding agents, announced by Recursive on 21 October 2026. It stores 39.8 billion parameters but activates only about 2.5 billion for each token, which is why it runs quickly on a laptop. The weights are free on Hugging Face under Apache 2.0, with a documented context of 262,144 tokens.
Flint is text only. Its reasoning is always on, it uses tools across several turns, and its stated knowledge cutoff is June 2026. Recursive says it "is designed to investigate codebases, fix bugs, implement features, and write tests".
Recursive was co-founded by Richard Socher, formerly Salesforce's chief scientist, to automate AI research, and Flint is its first model. The announcement says its Eureka Machine, a system that proposes, implements and tests research ideas, "helped develop nearly every part of Flint's model-building stack", down to Metal kernels for M4 and M5 chips. A small team built Flint from scratch in under four months.
Socher's launch post sums up the pitch: "Private, unmetered intelligence on your own machine." Recursive is also candid about the limits: "While Flint is very capable, it may need more guidance than the larger closed-source coding models you're used to." Its advice is to break complex work into smaller subtasks with explicit instructions.
Flint runs in Ollama, LM Studio, llama.cpp, Unsloth, vLLM and SGLang, plus rec, Recursive's own Mac engine. It is also free on OpenRouter and in OpenCode's free tier, but read the privacy note in the licence section first.
Which Mac runs Flint?
Recursive says Flint needs a Mac with at least 48 GB of unified memory, and its rec engine will not download the model on less. Other publishers go lower: LM Studio lists a 24 GB minimum, and Unsloth's 3-bit file is 18.5 GB. As of 23 October 2026, 48 GB is the comfortable tier and 32 GB the tight one.
| Mac memory | Build to use | What to expect |
|---|---|---|
| 16 GB | None. Unsloth's 2-bit builds need 13 to 15 GB in total. | Too tight. Pick a smaller model from the Ollama models list. |
| 24 GB | A 3-bit build: Unsloth's UD-Q3_K_XL GGUF (18.5 GB) or the mlx-community 3-bit MLX build (17.8 GB) | Short contexts only, around 32K. Unsloth says its 3-bit file fits 24 GB "at short contexts"; the MLX build is untested on a real 24 GB Mac. |
| 32 GB | 3-bit for headroom, or Ollama's 23 GB default with the context capped | Tight. One test measured 26.9 to 27.9 GB peak use, and MindStudio saw Ollama's build use just over 32 GB of GPU memory. Keep context near 32K; if ollama ps shows CPU use, go 3-bit. |
| 48 GB | rec with the 22.6 GB INT4 weights (M4 Pro, M5 Pro or M5 Max only), ollama run flint, or the 26.0 GB Q4_1 GGUF | Recursive's minimum and the tier behind its speed claims; its llama.cpp example runs the full 262,144-token context. |
| 64 GB and up | 8-bit (Unsloth's Q8_0, 42.3 GB); full BF16 is 80 GB, realistically a 128 GB Mac | Room for long sessions with other apps open; one test measured 117 tokens a second with rec on a 64 GB M5 Max. |
The file size is only the start: Recursive's documentation warns that "the model download size is only part of runtime memory". The KV cache that holds the conversation grows with context, and coding agents use a lot of context, which is why a 23 GB model gets uncomfortable on 32 GB.
rec supports only the M4 Pro, M5 Pro and M5 Max, so an M4 Max or older chip must use Ollama, LM Studio or llama.cpp. For buying advice with UK prices, see the Mac mini M5 Pro and MacBook Pro M5 pages.
How to run Flint with Ollama
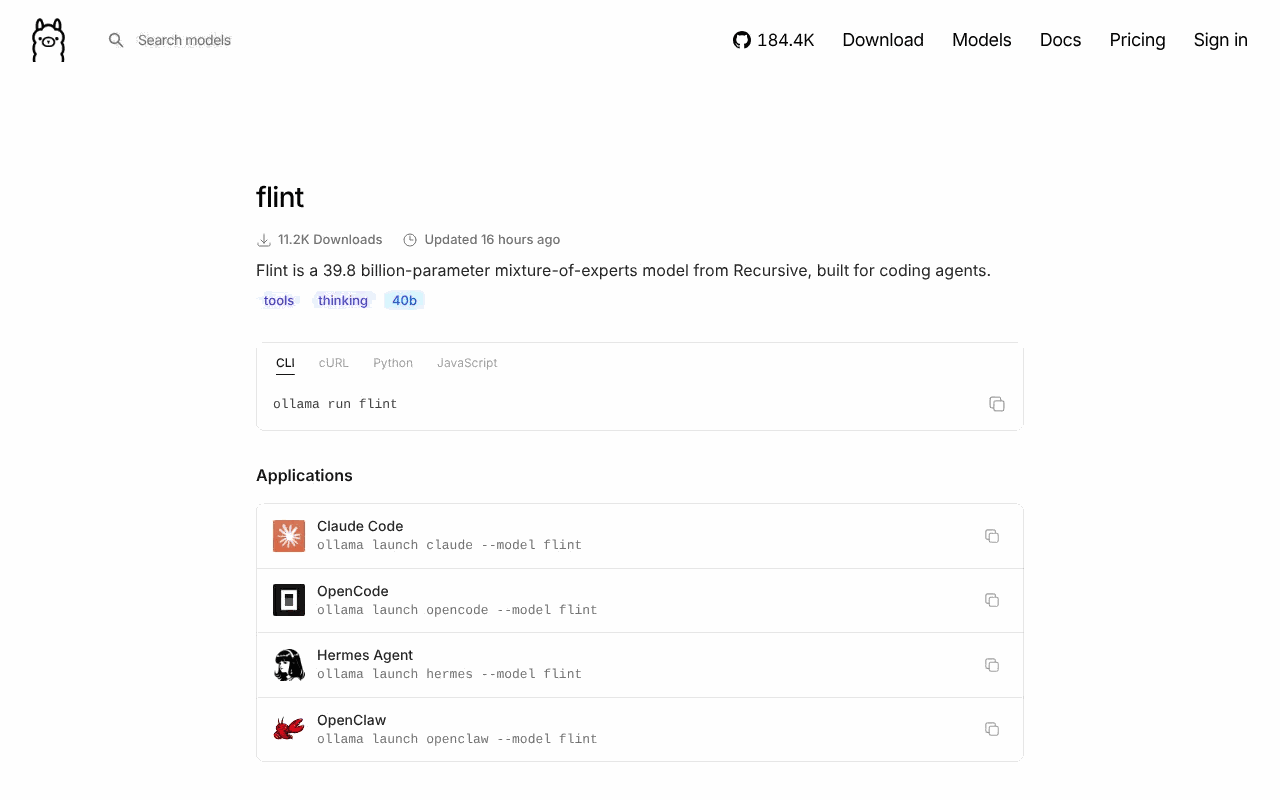
Ollama added Flint in version 0.40.8 on 21 October 2026, and the library name is simply flint: a 23 GB download with a 256K context window that takes text input and supports tools and thinking. Ollama's library listed 11.2K downloads on 23 October 2026. If Ollama is new to you, the Ollama guide covers installing it.
- Install or update Ollama. Download Ollama from ollama.com/download, or click the Ollama menu bar icon and choose Restart to update. Flint needs version 0.40.8 or later, released on 21 October 2026.
- Download and start Flint. In Terminal, run ollama run flint. The first run downloads 23 GB and opens a chat; type /bye to leave.
- Raise the context length. For coding agents, set the context to at least 64,000 tokens with the slider in Ollama's settings, or start the server with OLLAMA_CONTEXT_LENGTH=64000 ollama serve. On a 32 GB Mac, stay nearer 32,000.
- Check it fits in memory. Run ollama ps and confirm the PROCESSOR column says 100% GPU and the CONTEXT column shows the length you set.
- Connect a coding agent. From your project folder, run ollama launch claude --model flint for Claude Code, or ollama launch opencode --model flint for OpenCode.
The commands, as Ollama's documentation and model page give them:
ollama run flint
OLLAMA_CONTEXT_LENGTH=64000 ollama serve
ollama ps
ollama launch claude --model flint
Ollama's default context depends on GPU memory: 4k below 24 GiB, 32k from 24 to 48 GiB and 256k from 48 GiB. Its documentation says tasks like "web search, agents, and coding tools should be set to at least 64000 tokens", so set it yourself. The Ollama commands cheat sheet shows how to change it for a single chat.
Of the seven tags, flint, flint:40b and flint:40b-a2b are the same 23 GB build; the others include flint:40b-a2b-q4_1 (26 GB) and the full-precision flint:40b-a2b-mlx-bf16 (80 GB). Recursive's own Ollama guide uses the 23 GB QAT INT4 tag:
ollama run flint:40b-a2b-qat-int4Flint launched on macOS only in Ollama; version 0.40.9 on 22 October added Linux and Windows.
Run it in LM Studio or with MLX
LM Studio added Flint on launch day as recursivesi/flint, with a stated 24 GB minimum and 7.4K downloads by 23 October 2026. For MLX on Apple silicon there are two routes: Recursive's own rec engine with its 22.6 GB INT4 weights, or a 17.8 GB community 3-bit build aimed at 24 GB and 32 GB Macs.
LM Studio. Search for recursivesi/flint under Settings, Local Models, Explore, or use the lms command line tool that ships with the app. Recursive's documentation gives these commands:
lms get recursivesi/flint
lms load --identifier flint
lms chat flint
lms server start --port 1234
The server answers at http://127.0.0.1:1234/v1 as flint. LM Studio's entry uses the lmstudio-community GGUFs: Q4_K_M at 24.2 GB, Q6_K at 32.7 GB and Q8_0 at 42.4 GB, so treat its 24 GB minimum as a floor, not a recommendation. The LM Studio guide covers the app.
rec, Recursive's engine. rec runs the INT4 MLX weights with Recursive's own Metal kernels and sets up a coding agent for you. It needs an M4 Pro, M5 Pro or M5 Max with 48 GB or more, about 30 GB of free disk and Node.js 22. Install it and check your Mac:
curl -fsSL https://raw.githubusercontent.com/recursive-oss/rec/main/install.sh | bash
export PATH="$HOME/.local/bin:$PATH"
rec doctor
From your project folder, rec launch pi opens Pi, Recursive's recommended agent, and rec launch opencode opens OpenCode. rec serve exposes OpenAI and Anthropic-compatible APIs at http://127.0.0.1:11500, one request at a time.
rec launch pi
rec launch opencode
rec serve
rec stop
MLX on a 24 GB or 32 GB Mac. mlx-community/flint-mixed-3-4bit is an unofficial build that cuts Flint's experts from 4 to 3 bits. Its card says it is 17.8 GB, peaks at about 19.5 GB, and solved the same six coding tasks as Recursive's INT4. It runs with mlx-vlm 0.7.10 or later:
pip install -U mlx-vlm
mlx_vlm.generate --model mlx-community/flint-mixed-3-4bit --temperature 1.0 --top-p 0.95 --top-k 20 \
  --max-tokens 32768 --prompt "Write a Python function that merges overlapping intervals."
mlx_vlm.server --model mlx-community/flint-mixed-3-4bit --port 8080
On a 24 GB Mac, the card says macOS gives the GPU about 16 GB by default, and this raises it to 20 GB until the next restart:
sudo sysctl iogpu.wired_limit_mb=20480Caveats from the same card: in mlx-vlm 0.7.10, 41 of 85 tool calls failed in its OpenCode test because of wrong argument names, though every task still passed, and mlx-lm support is not yet released. For an app instead of Terminal, Unsloth Desktop on macOS runs Unsloth's 3-bit and 4-bit GGUFs.
How fast is Flint on a Mac?
Recursive measured Flint at 131.22 tokens a second on a 48 GB M4 Pro MacBook Pro with a 1,000-token prompt, falling to an average of 68.89 across contexts up to 128,000 tokens. Independent testers, as of 23 October 2026, broadly confirm the short-context figure but report much slower long agent sessions.
| Source | Mac and engine | Short context (tokens a second) | Long context (tokens a second) |
|---|---|---|---|
| Vendor claim: Recursive | M4 Pro, 48 GB, rec (MLX) | 131.22 | 68.89 averaged up to 128K |
| Vendor claim: Recursive | M4 Pro, 48 GB, llama.cpp | 87.98 | 47.58 averaged up to 128K |
| Vendor claim: Recursive, for comparison | M4 Pro, 48 GB, Qwen3.8-27B | 13.01 | 10.11 averaged up to 128K |
| Independent: a Kapitsa contributor in r/LocalLLM | M4 Pro, 48 GB, rec 0.1.0 | 126.6 | 35.2 at 128K |
| Independent: a Kapitsa contributor in r/LocalLLM | M4 Pro, 48 GB, llama.cpp b11804 | 79.6 | 23.8 at 128K |
| Independent: MindStudio | M4 Max, llama.cpp with an early Flint patch | About 110 | About 52 at 8K, 32 at 32K, 9 at about 115K |
| Independent: mlx-community build card | M5 Max, 64 GB, rec 0.1.0 | 117 over an 8,800-token answer | Not measured |
Ollama's launch post repeats the claim of more than 125 tokens a second on an M4 Pro MacBook Pro, and Recursive's README says rec is 1.4 to 2.6 times faster than llama.cpp on that chip. The Kapitsa tester works on a rival engine, so is independent of Recursive but not of the speed race.
The long-context column matters most for coding agents, which resend big prompts on every turn: MindStudio found Pi starts at about 17,000 tokens and OpenCode at about 26,000, and its real runs mostly landed between 40 and 60 tokens a second. Its llama.cpp patch carried, by the patch author's estimate, a 10 to 30 percent slowdown.
Even so, Flint stays well ahead: in Recursive's chart, comparable mixture-of-experts models ran at 58 to 69 tokens a second on the same M4 Pro, and Qwen3.8-27B at 13.
Flint as a local coding agent
Flint is built to sit behind a coding agent rather than a chat window. As of 23 October 2026 it plugs into Claude Code and OpenCode through Ollama, into Pi and OpenCode through Recursive's rec, and into Kilo Code through Kilo's Ollama provider. Whichever you pick, give it at least 64,000 tokens of context.
Claude Code. Ollama's model page gives one command, run from your project folder:
ollama launch claude --model flintThat points Claude Code at Flint on your Mac. Ollama's Claude Code guide says to "set a 64k+ context window" first, and Claude Code with Ollama covers the setup.
OpenCode and Pi. ollama launch opencode --model flint connects OpenCode through Ollama, and rec launch opencode or rec launch pi connect through Recursive's engine. Recursive recommends Pi, citing informal reports of roughly 1.5 times faster workflows than OpenCode.
Kilo Code. Add Ollama on the Providers tab in Kilo Code's settings (no API key needed) and choose ollama/flint; Kilo's documentation asks for at least 32K of context. Kilo Code was the biggest named app on OpenRouter's free Flint endpoint, at 7.64 billion tokens. See the Kilo Code review.
Give Flint small, explicit tasks, as Recursive advises, and keep your agent's approval prompts on: the model card warns it "can still produce incorrect or harmful content, faulty code, or inappropriate tool calls".
How Flint compares
Flint is the fastest of the four open coding models Mac owners most often weigh up, but not the strongest. On Recursive's own chart the dense Qwen3.8-27B scores higher on Terminal-Bench 2.1, 73.0 against 54.9, while running at a tenth of Flint's speed. All four are Apache 2.0 as of 23 October 2026.
| Flint | Qwen3.8-27B | Qwen3-Coder 30B | gpt-oss:20b | |
|---|---|---|---|---|
| Made by | Recursive (US) | Alibaba's Qwen team (China) | Alibaba's Qwen team (China) | OpenAI (US) |
| Total parameters | 39.8B | 27B (dense) | 30.5B | 21B |
| Active per token | About 2.5B | 27B | 3.3B | 3.6B |
| Ollama download (default tag) | 23 GB | 18 GB | 19 GB | 14 GB |
| LM Studio's minimum memory | 24 GB (Recursive says 48 GB) | 16 GB | 15 GB | 12 GB |
| Context in Ollama | 256K | 256K | 256K | 128K |
| Input | Text | Text and images | Text | Text |
| Licence | Apache 2.0 | Apache 2.0 | Apache 2.0 | Apache 2.0 |
| Speed on a 48 GB M4 Pro, short context (Recursive's chart) | 131.22 (MLX), 87.98 (llama.cpp) | 13.01 | Not in chart | Not in chart |
| Terminal-Bench 2.1 (Recursive's chart) | 54.9 | 73.0 | Not in chart | Not in chart |
| Ollama downloads, 23 October 2026 | 11.2K | 4.7M | 10.2M (all sizes) | 14.1M (all sizes) |
| Best for | Fast local coding agents on a 48 GB Mac | Better answers on a 32 GB Mac when speed matters less; reads images | A proven coding model for 32 GB Macs; Kilo Code's recommended local pick | 16 GB Macs: OpenAI says it runs within 16 GB |
Recursive's chart also puts Qwen3.8-27B ahead on SWE-bench Verified (75.6 against 74.2) and LiveCodeBench v6 (90.3 against 80.3), while Flint leads on the instruction-following tests IFBench and IFEval. Its 89.7% on SWE-bench Pro v2 is a score Recursive measured itself, and MarkTechPost notes it is not comparable to public SWE-Bench Pro scores.
So the choice is speed against judgement. On a 32 GB Mac, Qwen 3.8 is the safer pick for quality and fits more easily. On 48 GB and up, Flint is the one to try if waiting for a slow model has put you off local coding agents.
How many people use Flint?
Flint is two days old, so the public counters are small but climbing fast. The biggest single number: OpenRouter's activity data shows its free Flint endpoint handled 665,373 requests on 22 October 2026, its first full day. On the download side, Ollama's library showed 11.2K downloads of Flint on 23 October 2026.
| Counter | Figure, 23 October 2026 |
|---|---|
| flint in the Ollama library | 11.2K downloads |
| recursivesi/flint in LM Studio's catalogue | 7.4K downloads |
| Recursive's four official Hugging Face repositories | 15,773 downloads in the last month: 7,245 for the INT4 GGUF, 4,669 for the NVFP4 GGUF, 1,955 for the INT4 MLX build and 1,904 for the full checkpoint, which also has 606 likes |
| unsloth/flint-GGUF on Hugging Face | 33,277 downloads in the last month |
| lmstudio-community/flint-GGUF on Hugging Face | 15,263 downloads in the last month |
| OpenRouter free endpoint, 22 October 2026 | 665,373 requests and about 28.9 billion tokens |
| Richard Socher's launch post on X | 3.3 million views |
A download is not a person: one user may fetch several builds. The OpenRouter traffic is almost all input, 28.0 of the 28.9 billion tokens, which is what coding agents resending a codebase on every turn looks like.
What people say on Reddit and X
Early reaction to Flint on Reddit and X, gathered on 23 October 2026, splits cleanly: speed wins praise, judgement draws complaints. These are individual users' opinions and experiences, not tests I have run, and each quote is verbatim from the thread or post linked.
- On speed: "hitting 128 tok/s on a 40B model is wild for a laptop" - a user in r/LocalLLM, October 2026 thread
- Against Qwen 3.8, for Flint: "This model compares pretty well against Qwen3.8-27B on the benchmarks they published, while using less than a tenth of the active parameters per token" - a user in r/LocalLLaMA, October 2026 release thread
- Against Qwen 3.8, for Qwen: "If Qwen3.8-27B wouldn't exist this drop would be insane ngl" - a user in r/LocalLLaMA, October 2026 release thread
- On real coding work: "on my macs qwen 3.8-27b + splash engine is only slightly slower but a lot smarter" - a Mac user in r/LocalLLM after further tests, October 2026 thread
- On planning: "It cant even do planning. It just chats about what it might do without even looking at code." - a user in r/LocalLLM, October 2026 thread
- On how it was made: "Bullish on automated AI research. Early signs of self-improving AI, no doubt." - @omarsar0 of DAIR.AI, formerly of Meta AI, about 326,000 followers, October 2026 post
The praise is about speed; nobody disputes that Flint is quick on a 48 GB Mac. The complaints are about judgement: several users find Qwen3.8-27B smarter for real coding (the user above runs it with Splash, covered on the Qwen 3.8 page), which fits Recursive's advice to give Flint smaller, explicit tasks.
Ollama's launch post, which quotes Richard Socher's announcement:
And Recursive's own launch post:
Licence and safety: can you use Flint for work?
Flint's weights are under Apache 2.0, the same permissive licence as Qwen3.8-27B and gpt-oss, so as of 23 October 2026 a UK business can download, modify, fine-tune and use Flint commercially without asking Recursive. Run locally, Flint works offline and your code stays on your computer. The free hosted versions are a different matter.
Apache 2.0 asks you to keep the licence and copyright notices and mark files you change, and it grants a patent licence. The model card adds that "Hosted API terms and data practices are separate from the weight license".
The free hosted versions can train on your code. Recursive's terms for its hosted models say: "We may train on what you send." There is "no opt-in or opt-out except where the law gives you one", and you are told not to send passwords, API keys or personal data. OpenRouter lists Recursive as the only provider of its free Flint endpoint. Keep client code on the local routes, and for personal data at work see AI agents and UK GDPR.
Who makes it. Recursive Superintelligence, Inc. is a Delaware company with offices in San Francisco, according to its terms, and The New York Times reported in May 2026 that it also has an office in London. TechCrunch reports it raised 650 million US dollars (about £490 million) at a 4.65 billion dollar valuation (about £3.5 billion), from investors including GV, Nvidia and AMD Ventures.
Flint comes from a US company and was trained from scratch, so the questions in Is it safe to run Chinese AI models on your Mac? about whose values shaped a model apply differently than for Qwen. The plumbing rule is the same: a local model has no network access of its own, but an agent allowed to run commands can still do damage.
Frequently asked questions
What is Recursive Flint?
Recursive Flint is a free, open-weight coding model from Recursive, released on 21 October 2026. It has 39.8 billion parameters, of which about 2.5 billion work on each token, so it runs quickly on a Mac. It is text only, reasons before answering, uses tools across several turns and is licensed under Apache 2.0.
Will Flint run on a 32 GB Mac?
Yes, but it is tight. Ollama's default Flint download is 23 GB, an independent test on a 48 GB Mac measured 27 to 28 GB of peak use, and Recursive itself recommends 48 GB. On 32 GB, keep the context near 32,000 tokens and close other apps, or use a 3-bit build of about 18 GB for more headroom.
What is the Ollama command for Flint?
The command is ollama run flint, which downloads a 23 GB build and starts a chat. You need Ollama 0.40.8 or later, released on 21 October 2026. To use Flint with Claude Code, run ollama launch claude --model flint from your project folder.
How fast is Flint on a MacBook?
Recursive measured 131 tokens a second on a 48 GB M4 Pro MacBook Pro at short contexts. An independent test on the same chip found about 127 with Recursive's rec engine and about 80 with llama.cpp. Speed falls as context grows: one tester saw 40 to 60 in real agent runs and about 9 near 115,000 tokens.
Is Flint free to use for work?
Yes, the downloadable model is free for commercial use. The weights are under Apache 2.0, which allows commercial use, modification and redistribution as long as you keep the licence and copyright notices. The free hosted versions are different: Recursive's terms for its hosted models say it may train on what you send.
Is Flint better than Qwen 3.8?
Not on quality, but it is far faster. On Recursive's own chart, Qwen3.8-27B beats Flint on Terminal-Bench 2.1 (73.0 against 54.9) and SWE-bench Verified (75.6 against 74.2). Flint ran about ten times faster on a 48 GB M4 Pro: 131.22 tokens a second against 13.01.
Can I use Flint with Claude Code?
Yes, through Ollama. Run ollama launch claude --model flint from your project folder, after setting Ollama's context length to at least 64,000 tokens as Ollama's Claude Code guide advises. Expect to break big jobs into smaller steps, which Recursive itself recommends.
Does the free online version of Flint keep my code private?
No, not in the way running it locally does. Recursive's terms for its hosted models say it may train on your inputs and outputs, with no opt-out except where the law gives you one, and OpenRouter lists Recursive as the only provider of its free Flint endpoint. Running Flint through Ollama, LM Studio or rec keeps your code on your Mac.
Read next
- Can my Mac run this model? Local LLM memory calculator
- Qwen 3.8 on a Mac: the 27B on 32 GB and Flash-Next on 64 GB
- Claude Code with Ollama
- Ollama commands cheat sheet
- The 30 most downloaded Ollama models and which Macs run them
- Kilo Code review
- LM Studio guide
- Mac mini M5 Pro for local AI
- MacBook Pro M5 for local AI
Sources
- Introducing Flint, Recursive: parameter counts, Eureka Machine, speed claims, 512K and 256K context guidance, supported runtimes, quotes and the three launch charts - checked 23 October 2026
- Recursive Flint model card, RecursiveSI on Hugging Face: specifications, benchmarks, limitations, licence note and the benchmark chart - checked 23 October 2026
- Flint licence (Apache 2.0), RecursiveSI on Hugging Face: licence terms - checked 23 October 2026
- Flint INT4, RecursiveSI on Hugging Face: 22.6 GB MLX weights for rec - checked 23 October 2026
- Flint INT4 GGUF, RecursiveSI on Hugging Face: 26.0 GB Q4_1 file, 48 GB Mac requirement and full-context llama.cpp example - checked 23 October 2026
- Flint NVFP4 GGUF, RecursiveSI on Hugging Face: 22.9 GB file for NVIDIA GPUs - checked 23 October 2026
- RecursiveSI models, Hugging Face Hub API: downloads last month, likes and creation dates for Recursive's repositories - checked 23 October 2026
- Choose your setup, Recursive documentation: 48 GB requirement and memory planning - checked 23 October 2026
- Using Flint locally, Recursive documentation: always-on reasoning, context and output budget - checked 23 October 2026
- Ollama, Recursive documentation: the flint:40b-a2b-qat-int4 tag and /bye - checked 23 October 2026
- LM Studio, Recursive documentation: lms commands and server settings - checked 23 October 2026
- rec, Recursive documentation: Mac requirements, install, Pi recommendation and API settings - checked 23 October 2026
- OpenCode, Recursive documentation: OpenCode free tier and local connections - checked 23 October 2026
- rec, recursive-oss on GitHub: requirements, commands and the 1.4 to 2.6 times throughput claim - checked 23 October 2026
- Recursive Terms of Use: training on hosted inputs, what not to send, company and address - checked 23 October 2026
- flint, Ollama library: description, download count, capabilities, benchmarks and launch commands - checked 23 October 2026
- flint tags, Ollama library: tag names and download sizes - checked 23 October 2026
- Ollama v0.40.8 release notes, GitHub: Flint added, macOS first - checked 23 October 2026
- Ollama v0.40.9 release notes, GitHub: Flint on Linux and Windows - checked 23 October 2026
- Context length, Ollama documentation: default context by GPU memory, 64,000-token advice, ollama ps - checked 23 October 2026
- Claude Code, Ollama documentation: ollama launch claude and the 64k context advice - checked 23 October 2026
- FAQ, Ollama documentation: how to update Ollama on a Mac - checked 23 October 2026
- recursivesi/flint, LM Studio model catalogue: 24 GB minimum, context and download count - checked 23 October 2026
- flint-GGUF, lmstudio-community on Hugging Face: file sizes and downloads last month - checked 23 October 2026
- Flint: Run Locally Guide, Unsloth documentation: memory by bit width and the 24 GB note - checked 23 October 2026
- flint-GGUF, Unsloth on Hugging Face: file sizes and downloads last month - checked 23 October 2026
- flint-mixed-3-4bit, mlx-community on Hugging Face: 3-bit MLX build, commands, M5 Max speeds and tool-call caveat - checked 23 October 2026
- Recursive: Flint (free), OpenRouter: free pricing, provider, top apps and daily activity data - checked 23 October 2026
- Ollama provider, Kilo Code documentation: setup, model naming and 32K context advice - checked 23 October 2026
- Qwen3.8-27B model card, Qwen on Hugging Face: parameters, context and licence - checked 23 October 2026
- Qwen3-Coder-30B-A3B-Instruct model card, Qwen on Hugging Face: parameters, context and licence - checked 23 October 2026
- gpt-oss-20b model card, OpenAI on Hugging Face: parameters, 16 GB memory note and licence - checked 23 October 2026
- qwen3.8 tags, Ollama library: download size, context, input and download count - checked 23 October 2026
- qwen3-coder tags, Ollama library: download size, context and download count - checked 23 October 2026
- gpt-oss tags, Ollama library: download size, context and download count - checked 23 October 2026
- qwen/qwen3.8-27b, LM Studio model catalogue: 16 GB minimum - checked 23 October 2026
- qwen/qwen3-coder-30b, LM Studio model catalogue: 15 GB minimum - checked 23 October 2026
- openai/gpt-oss-20b, LM Studio model catalogue: 12 GB minimum - checked 23 October 2026
- Recursive Releases Flint, an Open-Weight 40B MoE Local Coding Model, MarkTechPost, 21 October 2026: report confirming file sizes and the SWE-bench Pro v2 caveat - checked 23 October 2026
- Recursive Flint Tested: Is This 40B Local Coding Model Worth It?, MindStudio, 22 October 2026: report of M4 Max speeds by context, agent prompt sizes and Ollama memory use - checked 23 October 2026
- Recursive launches Flint, a laptop coding model it says was largely built by AI, TechCrunch, 21 October 2026: funding, valuation, investors and Socher's background - checked 23 October 2026
- Notable Researchers Join $4 Billion Effort to Build Self-Improving A.I., The New York Times, 13 May 2026: offices in San Francisco and London - checked 23 October 2026
- AI Startup Recursive Superintelligence Secures $650M, Crowdfund Insider, 16 May 2026: valuation and San Francisco and London operations - checked 23 October 2026
- Ollama on X, 21 October 2026: launch post with speed claims and commands - checked 23 October 2026
- Richard Socher on X, 21 October 2026: launch post, quote and view count - checked 23 October 2026
- Recursive on X, 21 October 2026: official launch post - checked 23 October 2026
- LM Studio on X, 21 October 2026: day-one support and 24 GB guidance - checked 23 October 2026
- OpenRouter on X, 21 October 2026: free at launch - checked 23 October 2026
- @omarsar0 on X, 21 October 2026: comment on automated research - checked 23 October 2026
- Flint 40B A2.5B Q4 achieves 128 tok/s on MacBook Pro M4 Pro 48GB, r/LocalLLM, 22 October 2026: independent M4 Pro benchmark of rec, llama.cpp and Kapitsa with peak memory, and a user comment on speed - checked 23 October 2026
- RecursiveSI/flint (40B A2.5B), r/LocalLLaMA, 21 October 2026: user comparisons with Qwen3.8-27B - checked 23 October 2026
- a new model? Flint 40b, r/LocalLLM, 21 October 2026: user reports after testing on Macs - checked 23 October 2026